Connect with us

Technology

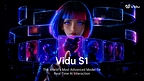
ShengShu Technology Unveils Vidu S1, Bringing Real-Time Interactive Generation to AI Video

Published

on

SINGAPORE, July 3, 2026 /PRNewswire/ — At the 2026 Global Digital Economy Conference, ShengShu Technology today unveiled Vidu S1, its next-generation video foundation model, delivering real-time interactive video generation that transforms AI video from creating single clips to enabling continuous, live interaction.

Vidu S1 supports real-time video conversations with voice-guided character control, allowing users to control AI avatars naturally through voice input while engaging in unlimited, continuous interactions. The model delivers 540P (960×540) resolution at 25 FPS (up to 42 FPS) and enables users to instantly create personalized interactive characters from a single image—whether a real person, an anime character, or even a pet—paired with a customizable voice. Together, these capabilities create a more natural, fluid, and immersive real-time interactive experience. Notably, the entire system runs on consumer-grade GPUs, significantly reducing the hardware requirements for real-time interactive video generation.

From Offline Video Generation to Real-Time Interaction

Most existing video generation models operate in an offline workflow: users submit a prompt, wait for the video to be generated, and then view the completed result. Once generated, the content remains fixed. Making changes to an AI avatar’s actions or the storyline typically requires generating a new video, limiting interaction to a one-way creation-and-viewing experience.

Vidu S1 introduces a real-time interactive video generation framework that enables users to provide voice input continuously throughout a real-time video conversation. The model processes voice input alongside conversational context and the current visual context, allowing subsequent video content to be generated and updated in real time.

Beyond real-time generation, Vidu S1 also advances voice interaction from simple lip synchronization to full AI avatar control. Rather than relying on audio-driven lip movements and predefined animation libraries, the model interprets the semantic meaning, intent, and emotional context of spoken input to generate synchronized lip movements, facial expressions, eye movements, gestures, body posture, and full-body actions in real time.

Together, these capabilities enable AI avatars to understand user instructions, respond naturally during conversations, and support continuous, real-time interaction.

Unlimited Real-Time Video Generation

Most video generation models today produce clips with a fixed duration, typically ranging from a few seconds to several tens of seconds. Once generation begins, users have limited ability to influence how the video evolves.

Vidu S1 adopts an autoregressive diffusion (AR + Diffusion) architecture. Rather than generating an entire video upfront, it continuously predicts and generates subsequent video content based on previously generated frames, current voice instructions, and conversational context. As users provide new instructions, the model updates the character’s expressions, movements, and subsequent actions in real time, enabling the interaction to evolve continuously throughout the conversation.

In addition to real-time interaction, Vidu S1 is a leading model for unlimited-duration real-time video generation. This requires more than continuous generation alone. The model must simultaneously preserve character identity, maintain natural and coherent motion, continuously process user input, and respond in real time throughout extended conversations.

By combining these capabilities, Vidu S1 enables persistent generative video interaction, allowing characters to remain responsive, visually consistent, and continuously interactive over extended periods.

540P at 25 FPS for Video-Call-Quality Interaction

Delivering real-time interactive video requires not only streaming generation, but also the resolution and frame rate needed to support natural, responsive conversations.

To meet these requirements, ShengShu Technology optimized Vidu S1 across model acceleration, inference, and system deployment, enabling real-time interactive video generation at 540P (960×540) resolution and 25 FPS, with support for up to 42 FPS.

At the model level, Vidu S1 is powered by ShengShu Technology’s inference acceleration techniques, including TurboDiffusion [1], low-bit SageAttention [2], and sparse attention methods such as SLA [3] and SpargeAttention [4]. Through few-step generation, model quantization, and optimized inference kernels, Vidu S1 significantly reduces the computational cost of generating each frame while supporting high-frame-rate output. This efficiency allows Vidu S1 to run real-time interactive generation on consumer-grade GPUs, rather than the large server clusters such workloads typically require.

At the system level, TurboServe [5], ShengShu Technology’s inference serving engine, efficiently schedules inference workloads while maintaining user inputs, character states, and visual context throughout an interaction. Compute resources are dynamically allocated based on the interaction state to support stable, low-latency real-time interactive video generation.

Together, these model- and system-level optimizations enable Vidu S1 to deliver continuous, stable, and responsive real-time interactive video generation throughout extended interactions.

These capabilities provide the technical foundation for applications such as real-time video conversations, interactive livestreaming, AI companionship, interactive gaming, and XR experiences.

Create Interactive Characters from a Single Image

Creating traditional AI avatars typically requires multiple images or video assets, followed by character modeling, rigging, lip-sync configuration, and dedicated training before the character can be used for interaction.

Vidu S1 introduces a fully generative workflow that eliminates the need for character-specific modeling and training. Users simply upload a single image, and the model captures the character’s identity, appearance, and visual style to generate synchronized lip movements, facial expressions, gestures, and full-body motion in real time.

Whether based on a real person, an anime character, or a pet, a single image can be turned into a real-time interactive character. Vidu S1 also supports customizable voices, enabling a consistent visual and vocal identity for each character.

By reducing character creation from a multi-step production pipeline to a single-image workflow, Vidu S1 makes personalized real-time interactive characters significantly easier to create.

A New Chapter for Interactive AI Video

As video foundation models continue to evolve, industry competition is expanding beyond image quality, generation speed, and video duration toward broader capabilities in real-time responsiveness, continuity, controllability, and interaction.

With Vidu S1, real-time interactive video generation enables AI video to move beyond pre-generated content toward dynamic, responsive experiences in which AI can understand user input, respond in real time, and evolve continuously throughout an interaction.

Looking ahead, Vidu S1 has the potential to support a wide range of applications, including AI companions, AI virtual influencers, interactive livestreaming, game NPCs, branded AI avatars, intelligent customer service, online education, and XR experiences. These capabilities enable AI avatars to evolve from one-time content assets into persistent, always-on interactive agents.

From generating individual video clips to enabling continuous interaction, and from one-way content creation to real-time two-way engagement, Vidu S1 expands the capabilities of video foundation models and lays the foundation for the next generation of interactive AI experiences.

Availability

Vidu S1 is now publicly available, enabling users to create and interact with AI avatars from their own custom images in real time. An API platform is also available for developers and enterprise partners to build real-time interactive applications.

Global Experience: https://www.vidu.com/vidu-stream

API: https://platform.vidu.com/live/landing

References
[1] TurboDiffusion: Accelerating Video Diffusion Models by 100–200 Times.
[2] SageAttention: Accurate 8-bit Attention for Plug-and-Play Inference Acceleration.
[3] SLA: Beyond Sparsity in Diffusion Transformers via Fine-Tunable Sparse-Linear Attention.
[4] SpargeAttention: Accurate and Training-Free Sparse Attention Accelerating Any Model Inference.
[5] TurboServe: Serving Streaming Video Generation Efficiently and Economically.

View original content to download multimedia:https://www.prnewswire.com/news-releases/shengshu-technology-unveils-vidu-s1-bringing-real-time-interactive-generation-to-ai-video-302817626.html

SOURCE ShengShu Technology

Continue Reading

Technology

HKAGE Showcases Gifted Students’ Learning Journeys at InnoCarnival 2026

Published

on

By

Promoting “Technology for Good” Through Innovation and Creativity 

HONG KONG, Oct. 24, 2026 /PRNewswire/ — The Hong Kong Academy for Gifted Education (HKAGE) has been invited to participate in InnoCarnival 2026, organised by the Innovation and Technology Commission. Under the theme “Technology for Good, Innovation for All”, HKAGE will showcase the learning journeys of gifted students who have completed programmes on AI robotic arms, underwater archaeology, etc., demonstrating how technology can be harnessed to address societal needs.

Having proactively aligned its work with the education development strategies of the Education Bureau (EDB), HKAGE fully supports the EDB’s Blueprint for Digital Education in Primary and Secondary Schools, which seeks to advance the digital transformation of school education in Hong Kong. Building on its Talent Development Model, HKAGE systematically develops programmes, provides diversified learning experiences and engages in cross-sector collaborations to nurture gifted talents equipped with innovative capabilities, technological literacy, and a strong sense of social responsibility. At the exhibition this year, HKAGE will present how students applied knowledge gained through gifted education programmes and learning experiences in areas such as artificial intelligence, quantum computing, environmental science, underwater archaeology and sustainable development to design socially conscious solutions. These experiences reflect the students’ ability to serve society with knowledge and respond creatively to diverse challenges.

Among the highlights is the learning journey of students in the “Artificial Intelligence Course: Creative AI Robotic Arm for Inclusion”. After acquiring foundational knowledge in artificial intelligence, robotics and sensor applications, students designed, tested and refined intelligent robotic arm prototypes through real-time data analysis and algorithms. With the aim of improving the quality of life for the elderly and caregivers, students explored various application scenarios for intelligent robotic arms. Another showcase features the “Environmental Science Course: Bat Echoes – Voices of the Night”. Through acoustic monitoring, the exhibition demonstrates how students recorded bat voices and analysed related activity data and characteristics. The programme enabled students to gain a deeper understanding of local biodiversity and explore practical approaches to ecological conservation.

The HKAGE exhibition booth also features an interactive photo-taking device, allowing visitors to take photos with different gifted programme themes and share the joy of learning.

On the first day of the exhibition, a “Build Your Own Glider Parent-Child Workshop” is specially organised by HKAGE for the visitors. Under the guidance of instructors and assisted by HKAGE students, participants will learn the basic principles of aerodynamics, including lift, gravity, thrust and drag. They will also learn to design, assemble and decorate their own gliders by using lightweight and durable materials, experiencing the joy of science and engineering.

Mr WONG Chung Po, Acting Executive Director of HKAGE, said: “The Academy is committed to providing gifted students with diversified learning platforms and encouraging them to transform knowledge into innovative practices that generate positive social impact. Participation in this exhibition not only provides students with a valuable learning experience that helps consolidate the knowledge acquired in gifted programmes, but also enables the public to better understand how gifted education nurtures a new generation of creative and socially responsible talents to jointly advance the philosophy of ‘Technology for Good’.”

InnoCarnival 2026 – The Hong Kong Academy for Gifted Education

Date:

24 Oct – 1 Nov

Venue:

The Hong Kong Science Park

Booth:

C08-09

Time:

10:00 – 17:00 (Mon to Fri)

10:00 – 18:00 (Sat & Sun)


About the HKAGE

Established in 2008 and subvented by the Education Bureau, the HKAGE offers gifted education services actively to local primary and secondary school students to unleash their potential. It also provides gifted education-related information and support for teachers, parents, and other relevant stakeholders.

View original content to download multimedia:https://www.prnewswire.com/apac/news-releases/hkage-showcases-gifted-students-learning-journeys-at-innocarnival-2026-302918606.html

SOURCE Hong Kong Academy for Gifted Education

Continue Reading

Technology

LEAP Group Relaunches HumanView, a Growth Intelligence System Built to Explain Why Customers Behave the Way They Do

Published

on

By

Reimagined from the ground up, HumanView pairs statistical modeling with expert analysts to turn millions of real-world customer signals into business decisions

LOUISVILLE, Ky., Oct. 23, 2026 /PRNewswire/ — LEAP Group today announced the relaunch of HumanView, its growth intelligence service. The new version has been rebuilt from the ground up and now has a dedicated home at leapgroupnetwork.com/humanview.

HumanView analyzes what customers say and do across social platforms, e-commerce sites, review platforms, search behavior and user-generated content, including signals from Reddit, TikTok, YouTube, Meta, Amazon and Walmart+ that general AI tools cannot always access. Because the data reflects unprompted, real-world behavior, it avoids the response bias built into surveys and focus groups.

The service works in three layers. HumanView captures signals at scale, decodes millions of records through validated statistical models such as regression, correlation and clustering, and then relies on experienced analysts to interpret the patterns. Clients receive clear, human-validated insights instead of another dashboard.

“Machines find the patterns. Humans find the point,” said Alan Gilleo, CEO at LEAP Group. “The first version of HumanView showed us how much customers reveal when nobody is asking them questions. This version is built to explain why they act the way they do, and to put those answers in front of everyone making decisions, from product to service to marketing.”

HumanView focuses on three areas:

Growth Intelligence: customer motivations and how people perceive a brand and its competitors

Market and Category Intelligence: product pain points, service friction, unmet needs and competitive gaps

Audience Intelligence: new segments, positioning opportunities and gaps in the market

Every model is designed and validated by data scientists and benchmarked before it informs a recommendation.

To learn more about HumanView, visit leapgroupnetwork.com/humanview.

About LEAP Group
LEAP Group is a boutique marketing agency holding company with offices in Louisville, Indianapolis, Cincinnati and Chicago. Guided by the belief that brands should “Market Less. Matter More.,” LEAP gives clients access to specialized experts across its entire network. Learn more at leapgroupnetwork.com.

View original content to download multimedia:https://www.prnewswire.com/news-releases/leap-group-relaunches-humanview-a-growth-intelligence-system-built-to-explain-why-customers-behave-the-way-they-do-302918557.html

SOURCE LEAP Group

Continue Reading

Technology

STEPHEN A. SMITH ADDRESSES WHITE HOUSE DINNER ATTENDANCE, REAFFIRMS COMMITMENT TO HBCUs AND PROTECTING CORPORATE INVESTMENT IN BLACK EDUCATION

Published

on

By

NEW YORK, Oct. 23, 2026 /PRNewswire/ — Stephen A. Smith, media mogul, New York Times bestselling author, and proud 1991 graduate of Winston-Salem State University, is addressing the public discussion surrounding his decision to attend a White House dinner with President Donald Trump, emphasizing his commitment to the long-term financial stability of Historically Black Colleges and Universities (HBCUs).

For Smith, the decision was rooted in a commitment to institutions that have educated generations of Black leaders, professionals, entrepreneurs, and public servants.

“I will always advocate for HBCUs and the students whose futures depend on them,” Smith said. “My reason for attending the White House dinner was to discuss the challenges these institutions face in securing long-term funding and to make the case that corporate America must continue to invest in them.”

Smith acknowledged federal support through the FUTURE Act while expressing concern that political tensions surrounding diversity, equity, and inclusion (DEI) could discourage private companies from supporting HBCUs. He maintains that these institutions deserve sustained corporate partnerships, philanthropic contributions, and public investment.

“If we truly believe in free-market capitalism, businesses should be able to support educational institutions and charitable causes without fear of criticism or repercussions,” Smith said. “HBCUs have made extraordinary contributions to this country. They deserve sustained public and private investment.”

Ashley Christopher, Esq., Founder and CEO of the HBCU Week Foundation, recognized Smith’s advocacy and decision to engage with the administration.

“Stephen A. Smith has been a powerful advocate for HBCUs, using his platform and influence to shine a national spotlight on our institutions,” expressed Christopher, “His continued support of HBCU Week helps advance our mission of connecting students with life-changing educational opportunities, and we are proud to have him as our ambassador.”

Since Smith became an HBCU Week Ambassador in 2019, the initiative has facilitated more than 15,000 on-the-spot college acceptances and raised and awarded more than $150 million in scholarships, according to the HBCU Week Foundation.

As public discussion continues, Smith is emphasizing the importance of ensuring HBCUs have the resources and partnerships needed to educate future generations and expand opportunities for students.

CLICK HERE to watch Smith’s full response to his White House visit.

MEDIA CONTACT:

media@mrsasinc.com

View original content:https://www.prnewswire.com/news-releases/stephen-a-smith-addresses-white-house-dinner-attendance-reaffirms-commitment-to-hbcus-and-protecting-corporate-investment-in-black-education-302918547.html

SOURCE Straight Shooter Media

Continue Reading

Trending