Connect with us

Technology

Vectris Discovers Recoverable AI Compute Capacity Inside Deployed GPUs, Demonstrating Up to 73% More Productive Capacity

Published

on

Waveform captures previously unrecovered capacity across NVIDIA H100, H200 and B200 infrastructure, with Vectris testing showing 30–73% higher throughput, 51–56% lower energy consumption and 22–42% faster workload completion.

BIRMINGHAM, Ala., Aug. 20, 2026 /PRNewswire/ — Vectris Labs today announced the discovery of deterministic structural patterns in AI inference that reveal recoverable compute capacity inside GPUs already deployed. The company has built Waveform, a control plane designed to capture that capacity and turn it into additional productive AI output—without retraining models, changing model weights or modifying GPU kernels. 

“Compute Yield is the economic expression of how much useful AI output we can produce from existing infrastructure.” Vinod Tipparaju, Vectris co-founder, CTO

WHY THIS MATTERS
AI infrastructure is entering a new phase. As demand for inference grows, the economics of AI increasingly depend not simply on how many GPUs an organization deploys, but on how much useful output those GPUs can produce within fixed constraints of power, capital and time.

Vectris calls this economic control point Compute Yield™: the amount of quality-equivalent accepted AI output produced from existing compute infrastructure. In practical terms, Waveform is designed to make existing GPU infrastructure produce more useful AI work without requiring additional GPUs or changes to the models.

THE DISCOVERY
Vectris’ work began with the observation that what appears irregular inside AI computation contains deterministic structural patterns that reveal where productive capacity is being lost. The company says those patterns make recoverable GPU capacity measurable, governable and capturable.

“We didn’t impose this structure on the computation—we discovered it was already there. The patterns are deterministic, and once we understood them, recoverable GPU capacity became something we could measure, govern and capture”, Said Vinod Tipparaju, Co-founder and Chief Technology Officer, Vectris Labs, “Compute Yield™ is the economic expression of that discovery—how much useful AI output we can produce from the infrastructure already in place.” 

THE PROOF
Waveform has now been tested across third-party NVIDIA, AMD and Intel silicon, providing cross-silicon evidence that the control plane is not confined to a single GPU vendor or architecture. Quantified results have been demonstrated on NVIDIA and Intel platforms.

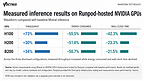
On commercially available NVIDIA H100, H200 and B200 GPUs in third-party RunPod infrastructure, Waveform increased productive GPU capacity on Mistral workloads while reducing both energy consumption and wall-clock time. No model retraining, model-weight changes or GPU-kernel modifications were required.

At the conservative +30% low end of the measured NVIDIA throughput range, a 10,000-GPU fleet operating at the same uplift would produce baseline-equivalent throughput comparable to 13,000 GPUs – the equivalent of 3,000 GPUs of additional productive capacity without expanding the physical fleet. This is an illustrative extrapolation, not a measured 10,000-GPU deployment.

Measured inference results on Runpod-hosted NVIDIA GPUs*
Waveform compared with baseline Mistral inference

GPU / Workload

Throughput

Energy Consumed

Wall-Clock

H100 / Mistral

+73 %

-55.5 %

-42.3 %

H200 / Mistral

+30 %

-51.6 %

-23.3 %

B200 / Mistral

+34 %

-50.7 %

-21.5 %

*Validation Note: Performance figures are Vectris-measured Mistral results on commercially available NVIDIA H100, H200 and B200 GPUs in RunPod infrastructure and are workload- and configuration-specific. They have not yet been independently reproduced in customer production. 

ARCHITECTURE-AGNOSTIC VALIDATION
On third-party Intel silicon, Waveform demonstrated 67% energy savings and a 32% reduction in time-to-result using the MLPerf LoadGen benchmark. Waveform has also been tested on third-party AMD silicon.

For operators, the evidence translates directly into capacity, cost and time: more useful AI output from installed infrastructure, less energy required to produce the work, and faster release of infrastructure for additional workloads.

WHAT WAVEFORM DOES
Waveform turns the discovery into an operational control point for AI infrastructure. It does not replace the optimized inference stack; it adds a control layer between serving infrastructure and the GPU, continuously identifying structural waste and reorganizing inference execution in real time.

The result is intended to complement existing inference infrastructure while targeting recoverable computational capacity that remains after conventional optimization. The objective is straightforward: more useful AI output from the infrastructure already deployed.

COMPUTE YIELD™
Vectris defines Compute Yield™ as the amount of quality-equivalent accepted AI output produced from existing compute infrastructure. It captures how efficiently installed infrastructure turns GPU capacity, energy and time into accepted AI output.

The company believes Compute Yield™ can become a new control point for AI infrastructure economics as operators increasingly balance compute availability, power constraints, capital investment and workload demand.

Vectris has completed technical demonstrations with AI-infrastructure and channel leaders and engaged a data-center advisory network representing approximately 300 MW of capacity.

COMMERCIAL AVAILABILITY
Waveform will launch October 1, 2026, with initial availability to a limited number of design partners. The company is moving from real-GPU proof toward commercial deployment.

THE BROADER AI INFRASTRUCTURE OPPORTUNITY
Vectris sees GPU inference as the first commercial application of its framework, not its endpoint. With Waveform now tested across NVIDIA, AMD and Intel silicon, the next frontier is to determine how far the same control principles extend across the broader AI infrastructure stack—including memory, data movement, networking, distributed compute, power and thermal systems. If validated across those domains, Waveform could become a broader control layer for the AI factory.

“The next phase of American leadership in artificial intelligence will depend not only on how much infrastructure we can build, but on how much more productive we can make the infrastructure already in place”, said Innovate Alabama Chairman Bill Poole, “The constraints around power, capital and compute are structural, and meeting exponential AI demand will require extracting greater value from every deployed system. Vectris is tackling that challenge from Birmingham with technology designed to increase the productive capacity of existing AI infrastructure—a powerful example of how consequential innovation from Alabama can address a problem of national economic and strategic importance.”

ABOUT VECTRIS LABS
Vectris Labs, Inc. is a Birmingham, Alabama-based AI infrastructure company behind Waveform, a control plane for Compute Yield™ in AI inference.

The Vectris team brings deep experience across GPU systems, AI infrastructure, cloud computing, performance engineering and large-scale computing environments, with backgrounds spanning AMD, Graphcore, Oracle Cloud Infrastructure, ByteDance, Mercedes-Benz, the U.S. Department of Energy and Oak Ridge National Laboratory.

That experience in understanding how computation behaves at the hardware and systems level led directly to Vectris’ discovery of deterministic structural patterns in AI inference—and to the development of Waveform as a way to measure, govern and capture the productive GPU capacity those patterns reveal.

Vectris was conceived and incubated in Birmingham by Thumos Capital. For additional information visit vectrislabs.ai. Book a Demo here.

MEDIA CONTACT
Melanie McCraney 
melanie@mccraneypr.com 

*VALIDATION AND DISCLOSURE
Performance figures are Vectris-measured Mistral results on commercially available NVIDIA H100, H200 and B200 GPUs in RunPod infrastructure and are workload- and configuration-specific. They have not yet been independently reproduced in customer production. The 10,000/13,000-GPU example is illustrative, not a measured fleet deployment. Third-party names do not imply endorsement. Quotes, titles and public references remain subject to approval before publication.

View original content to download multimedia:https://www.prnewswire.com/news-releases/vectris-discovers-recoverable-ai-compute-capacity-inside-deployed-gpus-demonstrating-up-to-73-more-productive-capacity-302855697.html

SOURCE Vectris Labs

Continue Reading

Technology

Harness Introduces the Infrastructure Efficiency Loop, Turning Cloud Waste into Reviewed Infrastructure as Code Changes

Published

on

By

Harness’s Cost Management and Software Delivery Agents open pull requests for cloud savings, and Infrastructure Blast Radius scores each change’s risk before engineers approve it

SAN FRANCISCO, Nov. 12, 2026 /PRNewswire/ — Harness, the Autonomous SDLC Platform™ company, today announced general availability of the Infrastructure Remediation Agent and Infrastructure Blast Radius Agent. Paired with the Harness Cost Management Agent, the Remediation Agent creates the Infrastructure Efficiency Loop, a continuous workflow that takes cloud waste from finding to fix without a ticket in between, while Blast Radius scores the risk of each change before it is approved.

AI is accelerating software development, and every new application needs infrastructure underneath it. Platform teams are provisioning faster while under pressure to hold cloud spend down, and the Harness 2026 State of AI in FinOps report puts waste at 26% of cloud and AI spend.

Savings opportunities are easy to find and slow to act on. Each one becomes a ticket, an engineer translates it into infrastructure code, and the fix competes with everything else on the backlog. Tools that change cloud resources directly skip the queue, but they can leave live infrastructure out of sync with the code meant to manage it.

The Infrastructure Efficiency Loop

The Infrastructure Efficiency Loop makes optimization a continuous part of how engineering works. It runs in four stages:

Identify: The Cost Management Agent surfaces cost optimization and drift findings.Remediate in code: The Infrastructure Remediation Agent turns a finding into an IaC pull request.Validate and apply: A pipeline checks the plan and Infrastructure Blast Radius scores its risk. Engineers review and merge, and existing pipeline controls govern how the change is applied.Track and repeat: The Cost Management Agent tracks which recommendations have been applied and keeps surfacing new opportunities as infrastructure and costs change.

“I’m most excited about the potential to turn these cost management insights directly into action. Instead of stopping at a recommendation we send out via email or Jira, having the platform create a pull request with the proposed remediation for our application teams changes the experience entirely. In our environment, these pull requests trigger a plan in Infrastructure Deployments, which will help give the context engineers need to confidently review and implement the change,” said Dustin Mason, Principal Cloud Engineer at Citizens Bank.

New Capabilities For Platform Teams

The Cost Management Agent now works inside Harness Infrastructure Deployments, bringing the costs an organization pays, including negotiated discounts and enterprise agreements, into infrastructure workspaces. Cost optimization and drift findings appear in workspace Insights, next to the infrastructure engineers already manage. The agent infers applied status automatically for most implemented recommendations, and users can mark others as applied.

From any finding, the Infrastructure Remediation Agent generates an IaC change and opens a pull request. A pipeline can run plan-based checks and write the results back as pull request comments, and engineers keep control of the merge.

To safeguard these changes, the new Infrastructure Blast Radius Agent analyzes Terraform and OpenTofu changes and provides approvers with a risk score from 1 to 10, a plain-language explanation of the risk, and a dependency graph of the resources behind the change. Teams can use the score and risk level to require additional approvals for higher-risk changes, so the review effort goes where the risk is.

Better Together On The Autonomous SDLC Platform

“We’re launching the Infrastructure Efficiency Loop so platform teams can finally act on cloud savings without trading away control,” said Patrick Brogan, Field CTO at Harness. “Our customers already know where their waste is. What slows them down is the handoff between a finding and a fix, and that is the work we are taking off their plates. Engineers stay in charge of every change, and the savings move at the pace their teams ship.”

The Harness Cost Management and Software Delivery Agents draw on the SDLC Knowledge Graph, the shared context across an organization’s services, pipelines, deployments, and policies. That context lets the Cost Management Agent point to the right resources and lets the Infrastructure Remediation Agent write changes that fit the workspace they land in. Every action runs under the same identity, policy, and approval controls as the rest of the delivery process, so teams can move faster without giving up control of how changes are made.

Availability

The Infrastructure Remediation Agent, cost context in Harness Infrastructure Deployments workspaces, applied-status tracking in the Cost Management Agent, and Infrastructure Blast Radius are generally available today. See Harness Infrastructure Deployments in action by requesting a demo.

About Harness
Harness is the Autonomous SDLC Platform company, enabling engineering teams and agents writing code to deliver software quickly, reliably, and securely. Harness’s platform includes the Software Delivery, Security Testing, Runtime Protection, and Cost Management Agents. The Agent Harness ties them together, sharing context from the Software Delivery Knowledge Graph and governing every action through identity, permissions, policy, and verification. Companies like United Airlines, Morningstar, and Choice Hotels use Harness to accelerate releases by up to 75%, cut cloud costs by up to 60%, and improve efficiency by up to 10x. Based in San Francisco, Harness is backed by Goldman Sachs, Menlo Ventures, IVP, Unusual Ventures, and Citi Ventures.

View original content to download multimedia:https://www.prnewswire.com/news-releases/harness-introduces-the-infrastructure-efficiency-loop-turning-cloud-waste-into-reviewed-infrastructure-as-code-changes-302938049.html

SOURCE Harness

Continue Reading

Technology

Clawlab Raises Over $15 Million in Pre-A3 Funding to Bring Smart Knitting Home

Published

on

By

SHENZHEN, China, Nov. 12, 2026 /PRNewswire/ — Clawlab, a technology startup developing smart tools for textile creation, has raised more than $15 million in a Pre-A3 funding round led by miHoYo. Vision Plus Capital and Shunwei Capital also increased their investments through super pro rata participation. The round brings Clawlab’s total funding to approximately $25 million across four equity rounds. Its shareholder base includes Sequoia China, Shunwei Capital, YM Capital, Vision Plus Capital, and miHoYo, bringing together leading venture capital firms and a strategic corporate investor.

Investors Back Clawlab’s Vision for a New Consumer Category

With AI software commanding much of the market’s attention, Clawlab’s more than $15 million funding round reflects investor interest in a different opportunity: the untapped consumer potential of smart knitting.

The opportunity comes from a gap between rising consumer demand and the tools available to meet it. Interest in personalized, hands-on creation is growing, yet most knitting equipment remains designed for factories and professional users. Pattern development, stitch control, and machine operation still require specialist expertise. The category lacks a desktop device capable of bringing industrial-grade knitting capabilities within reach of individual creators.

Clawlab is addressing that gap with the world’s first smart knitting machine designed for home use. It turns an image or idea into a finished knitted item, handling pattern preparation, stitchwork, and repetitive production while leaving the design, colors, and intended use to the user.

That flexibility supports a wide range of applications, from scarves and doll clothes to pet accessories and personalized gifts. A hobby project can also grow into custom work or a small business. Clawlab is set to unveil this smart knitting machine to a global audience at CES 2027.

The Engineering Foundation Behind Clawlab

Bringing professional knitting equipment into the home involves more than reducing its size. The real challenge is translating complex engineering into a product that feels intuitive to everyday users. Clawlab’s founder and CEO Wenxin Hu previously worked as a hardware engineer at DJI and Meituan, while most members of the company’s core R&D team are also former DJI employees. Together, they bring experience developing consumer-grade smart hardware and other technically complex products.

That background has shaped Clawlab’s approach to product development. Rather than simply miniaturizing existing equipment or adding digital features, the company is rethinking the knitting experience across hardware, software, and interaction design around the needs of individual creators. The technology takes on the complexity, while users retain control of the creative process.

The Long-Term Vision in Knitting

Clawlab chose knitting based on a simple premise: textiles meet one of the most basic and enduring needs of everyday life.

“Textiles meet a broad, long-standing need in everyday life. Standardized products are abundant, but consumers’ desire for personal style, customization, and emotional expression remains underserved,” said Wenxin Hu. “We want to reconnect ideas, design, and production so that people without professional training can create through knitting.”

Their longer-term ambition is to make knitting an everyday medium of expression. Smart knitting equipment, design software, and a creator community can help people turn ideas, memories, and care for others into one-of-a-kind pieces they can hold, share, and pass on.

About Clawlab

Clawlab is a technology startup founded in 2023 that develops smart tools for textile creation. It is building the future of knitting through a combination of innovative knitting technologies and a connected maker community. Its mission, “Push knitting forward. Bring more ideas to life,” is to develop the tools and technology that help more people turn what they imagine into something they can hold. Clawlab’s vision is to make knitting an everyday language for expression, much like words and pictures, through which people can tell their stories, preserve memories, and connect with others. For more information, please visit www.clawlab.com

View original content:https://www.prnewswire.com/news-releases/clawlab-raises-over-15-million-in-pre-a3-funding-to-bring-smart-knitting-home-302937289.html

SOURCE Clawlab

Continue Reading

Technology

Infor and Anthropic Announce Partnership That Turns Insights into Actions for Manufacturing Operations

Published

on

By

Manufacturers can connect Claude to Infor’s industry-specific applications to ask questions, get answers, and take approved actions within Claude

CHICAGO, Nov. 12, 2026 /PRNewswire/ — Infor and Anthropic today announced a partnership that combines Claude with Infor’s deep expertise in manufacturing operations. Infor Industry AI for Claude supports a range of roles, including production planners, buyers and customer service representatives. Users can work in either Infor or Claude, ask questions in plain language, review data and insights from Infor systems, and execute recommended actions. Infor’s industry logic, process controls, and governance guardrails are all made available to Claude. Customers can now update a purchase order or fix an at-risk production order in Infor, right from the Claude conversation.

Experience the full interactive Multichannel News Release here: https://www.multivu.com/infor/9413252-en-Infor-and-Anthropic-Announce-Partnership

A Partnership Built on Trust

Claude is Infor’s preferred AI assistant for interacting with Infor products and Claude models are the preferred models powering Infor’s Industry AI solutions. Infor Industry AI for Claude works through a new plugin and connector, and the permissions and governance controls configured in Infor still determine what each person can see and do in Infor.

Why industry depth matters

Infor’s solutions are built to meet the unique requirements across discrete manufacturing, process manufacturing, distribution and services industries. Within manufacturing industries, Infor understands the critical workflows, complex relationships with customers and suppliers, and interdependencies that are core to operations. Customers can get recommendations in conversation and, once a user reviews and approves, have the work carried out in Infor. Skills built for Claude carry Infor’s manufacturing knowledge into each conversation. With approval, actions include creating a purchase order, reallocating stock to an urgent order, shifting production lines after unplanned downtime, and shipping an order.

“Manufacturers need answers grounded in how their business really runs, and then the ability to act on them,” said Kevin Samuelson, CEO of Infor. “Infor brings the industry depth and governed controls, allowing customers to access that industry-specific context in Claude or in Infor, wherever they choose to work. When AI begins managing your workflows, the system underneath matters more, not less.”

“Manufacturing depends on expertise spread across many systems, and a large part of the day goes to moving information between them,” said Lauren Collett, Head of Enterprise Industries GTM at Anthropic. “Infor knows how manufacturers plan, buy, and deliver, and connecting Claude to its systems can give planners, buyers, and customer service teams more time for the decisions that depend on their judgment.”

“Our employees need easy access to the precise answers available to them within Infor systems without delay. Being able to ask a question naturally in the interface where they work, and get trusted, relevant information from the right source is an immediate productivity gain,” said Jessica Vincent, Vice President of Business Solutions, Oldcastle APG. “Connecting Claude with Infor can make critical business data easier to access while maintaining the governance our organization requires, helping people become productive and make informed decisions faster.”

Built around how manufacturing really works

Examples include:

Production planners can ask why a production order is at risk, see whether the cause is a material shortage, limited machine capacity or a labor shortage, and start corrective action in Infor, all from Claude.Customer service representatives can check availability, warehouse locations and production options, then rush an order or confirm a delivery date while the customer is still on the line.Buyers can see which production or customer orders a late receipt will affect, identify alternative suppliers, and place replacement purchase orders in one guided conversation.

What manufacturers can expect

Easy to use. Users can ask questions in everyday language and move from question to action in one place. They can also switch to Infor’s role-based workspaces when they need a more detailed view of the business.

Precise. Infor provides Claude the language and logic of manufacturing. For example, item, SKU, and product are understood as the same thing. Because the connector recognizes the user’s identity, responses reflect each person’s role and site. This context is configured once for the whole company rather than taught one user at a time.

Governed. Single sign-on and role-based entitlements, drawn from existing Infor permissions, determine what each person can see and do in Infor. Actions taken through the connector are subject to authorization controls and recorded in Infor.

Open and connected. Manufacturers run on many systems. The connector is built on the open Model Context Protocol standard, allowing teams to work across Infor and other compatible tools they rely on without leaving Claude.

Availability

Infor Industry AI for Claude is now available to select Infor Velocity Suite customers. Customers need their own Claude license, and an administrator must activate the Infor connector. Infor intends to add roles, skills and applications over time. For more information, visit https://www.infor.com/platform/enterprise-ai/claude-connector.

About Infor
Infor is a global leader in business cloud software specialized by industry. We develop complete solutions for our focus industries. Infor’s mission-critical enterprise applications and services are designed to deliver sustainable operational advantages with security and faster time to value. Over 60,000 organizations in more than 175 countries rely on Infor’s 17,000 employees to help achieve their business goals. As a Koch company, our financial strength, ownership structure, and long-term view empower us to foster enduring, mutually beneficial relationships with our customers. Visit www.infor.com.

Media contacts
Infor Communications: inforpr@infor.com

FAQ

Which customers can use Infor Industry AI for Claude?
It is available to select Infor Velocity Suite customers. Infor plans to add roles, skills and applications over time.

What do customers need to get started?
Customers need their own Claude license, and an administrator must activate the Infor in Claude connector.

Does Claude make decisions without user approval?
No. Infor’s plugin for Claude is designed to get a user’s explicit approval before each change in Infor.

How is access to data controlled?
Single sign-on and role-based entitlements, drawn from existing Infor permissions, determine what each person can see and do in Infor. Actions taken through the connector are subject to authorization controls and recorded in Infor.

Does this work with other tools?
Yes. The connector is built on the open Model Context Protocol standard, so teams can work across Infor and other compatible tools.


View original content:https://www.prnewswire.com/news-releases/infor-and-anthropic-announce-partnership-that-turns-insights-into-actions-for-manufacturing-operations-302938160.html

SOURCE Infor

Continue Reading

Trending